 TabTasker
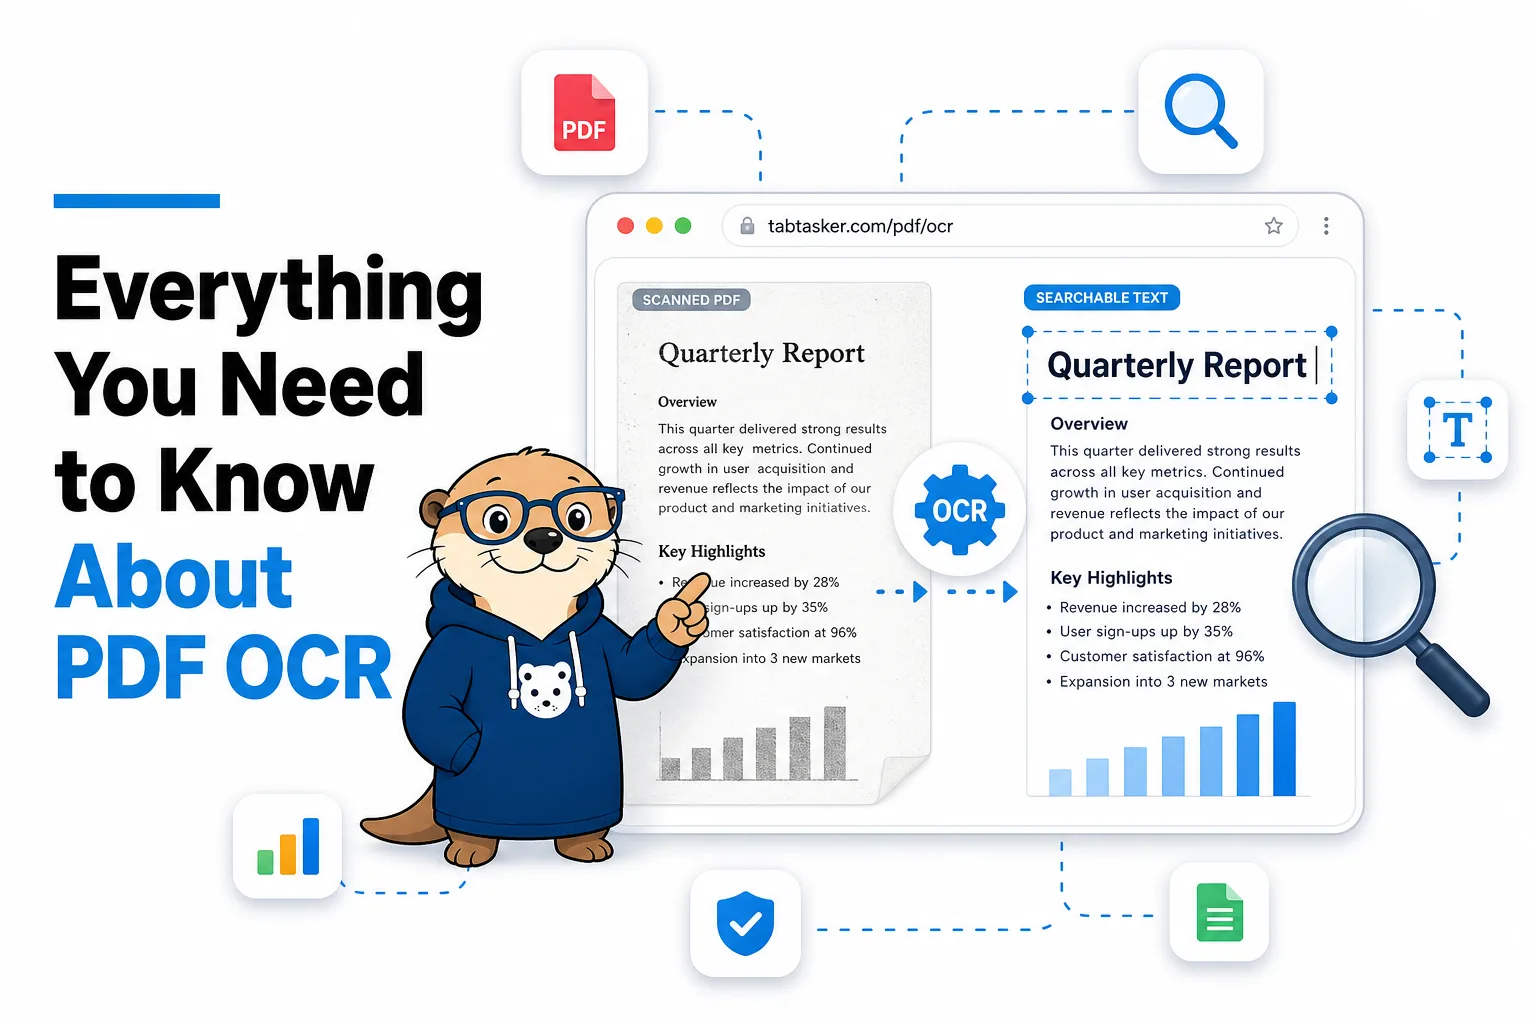
The scanned PDF problem
You receive a PDF that looks perfectly normal. You can read it, print it, share it. But you can't search it. You can't copy text from it. Screen readers can't read it.
That's because it's not a real text document. It's a picture of a document. Every page is an image, and to your computer, it's no different from a photograph.
What is OCR?
OCR (Optical Character Recognition) is the process of analyzing an image and identifying the text it contains. Modern OCR is remarkably accurate, especially for clean, printed text.
When you apply OCR to a scanned PDF, the tool:
- Analyzes each page as an image
- Identifies individual characters and words
- Determines their positions on the page
- Creates an invisible text layer behind the image
The result looks identical to the original, but now you can search, copy, and select text.
Why OCR matters
OCR matters beyond just convenience:
- Accessibility. Screen readers need text, not images. OCR makes scanned documents accessible to visually impaired users.
- Searchability. Finding information in a 200-page scanned document without OCR means reading every page manually.
- Compliance. Many regulations require documents to be searchable and accessible.
- Workflow. Copying text from a non-OCR PDF means retyping. For legal and medical documents, that's a liability.
How good is modern OCR?
The accuracy depends heavily on the source quality:
- Clean digital scans (300 DPI or higher): 98 to 99 percent accuracy for printed text.
- Phone photos of documents: 85 to 95 percent accuracy, depending on lighting and angle.
- Handwriting: Variable. Some engines handle neat handwriting well; most struggle with cursive.
- Low-resolution or blurry scans: Accuracy drops significantly. Garbage in, garbage out.
OCR in your browser
TabTasker's OCR tool uses Tesseract.js, an open-source OCR engine that runs entirely in your browser. Your scanned PDF never leaves your device. For single-page images rather than full PDFs, use the Image OCR tool, which extracts text from screenshots and photos with the same local engine.
The process:
- Drop your scanned PDF into the tool
- Select the language(s) in the document
- Run OCR, and the engine processes each page locally
- Download the searchable PDF
Limitations to know
- OCR works best with printed text. Handwriting is hit-or-miss.
- Complex layouts (multi-column, tables, forms) may not be perfectly reconstructed.
- Very old or degraded documents may need preprocessing (contrast adjustment, deskewing) before OCR.
- Large documents take time. OCR is computationally intensive, even in modern browsers.
Bottom line
If you have scanned PDFs, run OCR on them. It's the single most useful thing you can do to make those documents actually usable. And doing it locally means your documents stay private.
How to improve OCR accuracy
If you are getting poor results, the input quality is almost always the cause. Here are the most effective ways to improve accuracy before running OCR:
- Scan at 300 DPI or higher. This is the minimum resolution for reliable character recognition. 600 DPI is better for small or dense text.
- Use grayscale or black-and-white. Colour scans can interfere with character detection. Converting to grayscale often improves results.
- Ensure the page is straight. Even a few degrees of rotation reduces accuracy significantly. Deskewing before OCR makes a real difference.
- Improve contrast. Light, faded text on a grey background is hard for OCR engines to detect. Increasing contrast before scanning helps.
OCR and document accessibility
Beyond personal convenience, OCR has important accessibility implications. Screen readers used by visually impaired users cannot interpret image-based PDFs. They read the text layer, and if there is none, the document is silent. Running OCR on scanned documents makes them accessible to people who rely on assistive technology.
For organisations publishing documents publicly, this is often a legal requirement. Many accessibility standards and regulations require that digital documents be machine-readable. OCR is how you get there for scanned content.
Privacy considerations for OCR
Scanned documents often contain the most sensitive content: signed contracts, tax forms, medical records, passports. Uploading these to a cloud OCR service means sending their full contents to a third-party server.
TabTasker's OCR tool uses Tesseract.js running entirely in your browser. Your scanned PDF is never transmitted. The text layer is built locally and the result downloads directly to your device. Once a PDF is searchable, you can also feed it into the PDF to Podcast tool for an audio version, or redact sensitive content now that the text layer exists.