 TabTasker
The file is too big to email, again
You have a video to send. Maybe it is a 3 GB screen recording, a folder of raw photos from a shoot, or a design export that your client needs today. You attach it to an email and the email bounces: too large. So you upload it to a cloud drive, wait for the progress bar to crawl to 100 percent, generate a share link, send the link, and then your recipient downloads the whole thing back down again. Your file made a round trip through a company's servers, sat there as a copy, and took twice as long as it should have.
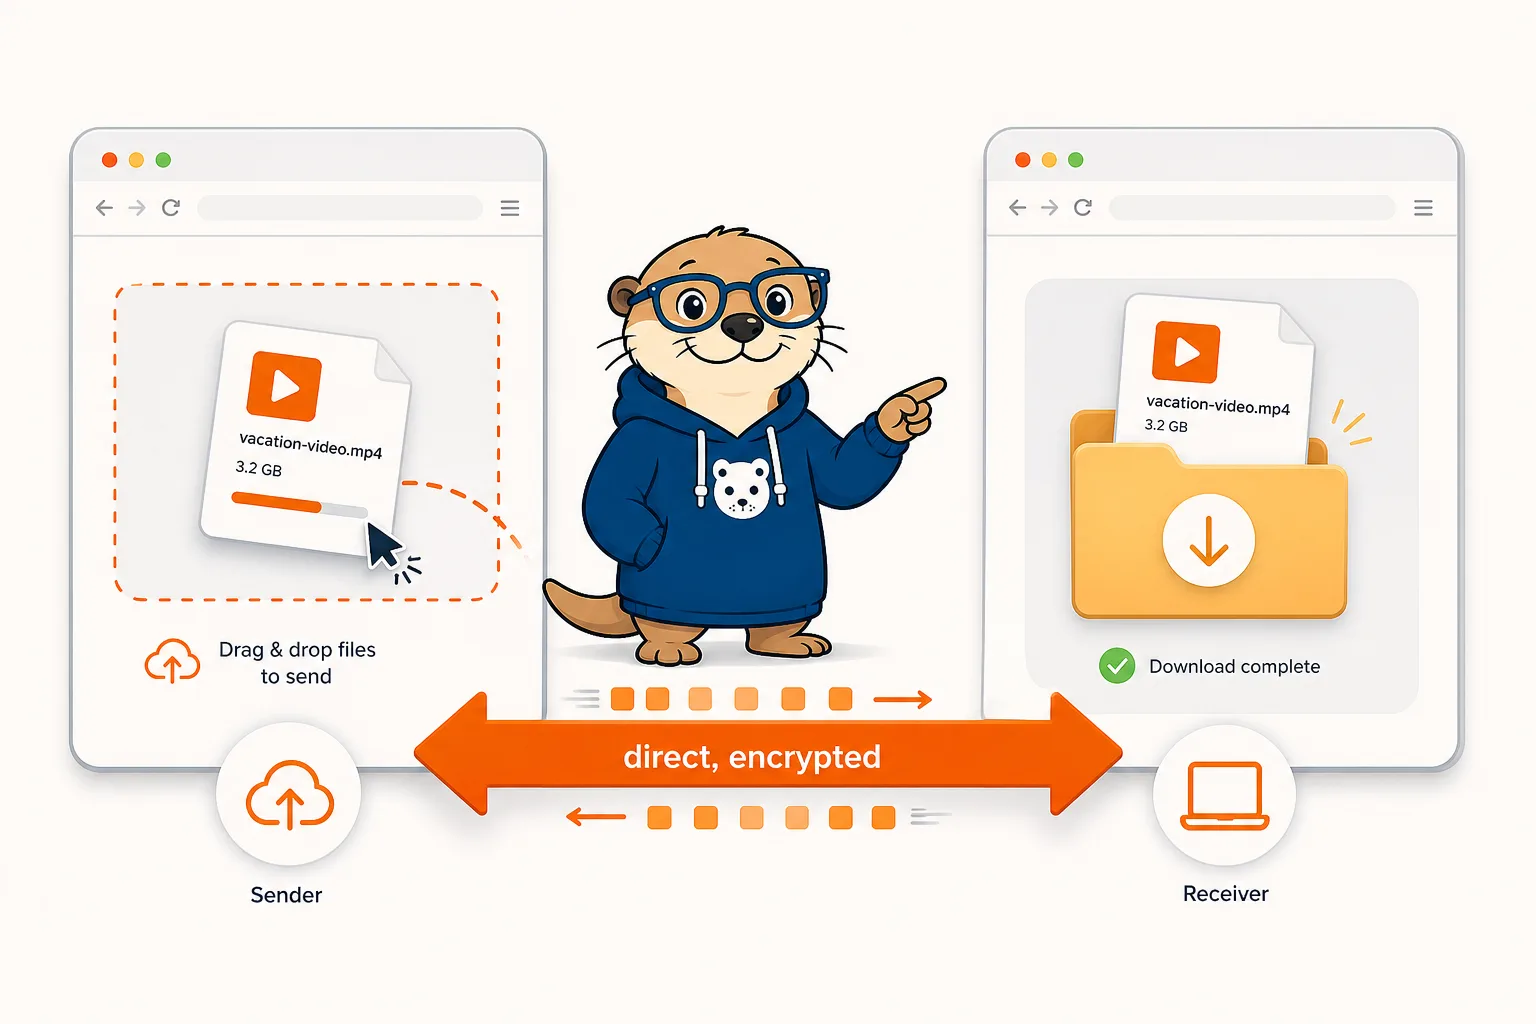
There is a more direct way. A browser can open a private connection straight to another browser and stream the file across it, device to device, with no upload step, no server copy, and no size limit. You drop the file, the other person gets a code or a link, and the bytes flow directly from your machine to theirs.
This guide explains how that works, from the everyday "just send me the file" all the way down to the flow-control math and the disk-streaming APIs that let a browser move a file larger than its own memory. Read as far as you need.
If you want to try it now, TabTasker's file share sends files directly between browsers, with no upload and no account. The rest of this article is about what happens when you drop that file.
The everyday version: what is browser-to-browser file sharing?
Three plain ideas.
First, it is direct. The file does not get uploaded to a server and then downloaded by the other person. It travels on a connection that runs straight from your browser to theirs. There is no copy sitting in the middle.
Second, there is no upload step. With a cloud drive, you wait for the upload to finish before the other person can even start downloading. With a direct transfer, the sending and receiving happen at the same time, the bytes leave your device and arrive at theirs in one continuous flow. For a large file, that alone roughly halves the wall-clock time.
Third, there is no account and no size limit. You do not sign up. And because nobody is storing your file, there is no storage quota to bump into. The only limits are your connection speed and your patience.
Here is how it stacks up against the usual ways people move a file.
| What you want | Email attachment | Cloud drive link | USB stick | Browser-to-browser |
|---|---|---|---|---|
| Big files (GBs) | No, hard size caps | Yes, within quota | Yes | Yes, no size limit |
| Speed | Slow, and capped | Upload then download | Fast but physical | Direct, sender and receiver at once |
| A copy left on a server | Yes (mail servers) | Yes, until you delete it | No | No, nothing stored |
| Account needed | Yes | Usually | No | No |
| Works across the room or the world | World | World | Room only | Both |
| Private by default | No | Depends on the vendor | Yes | Yes, direct and encrypted |
The pattern: a direct browser transfer combines the privacy of a USB stick with the reach of the internet, and removes the upload wait and the storage cap that make cloud drives tedious for big files.
Who uses this, and when
A videographer sends a client a 5 GB edit without paying for a file-transfer service or splitting it into parts.
A photographer hands off a wedding gallery, hundreds of full-resolution images, straight to the couple, with nothing sitting on a third party's server afterward.
Anyone moving a file between their own two devices, laptop to phone, work machine to home machine, can do it directly instead of bouncing it through the cloud.
A lawyer or accountant sends a sensitive document to a client knowing the file never rests on anyone else's infrastructure, only on the two devices that are meant to have it.
The common thread: files that are large, sensitive, or both, where uploading to a server is either too slow or too risky.
How it works, part one: the same direct pipe as a video call
If you have read the guide to browser-to-browser video calls, the foundation will look familiar, because it is the same. File sharing uses WebRTC, the browser's built-in real-time connection technology, and specifically its data channel: a direct, encrypted, peer-to-peer pipe that can carry arbitrary bytes.
Getting that pipe open follows the same three-step dance a video call uses, so we will keep it brief here:
- A tiny signaling server helps the two browsers exchange a one-time introduction (an offer and an answer). It never touches the file, only the handshake.
- ICE and STUN find a network path between the two devices through the maze of home routers and NAT.
- Once connected, the browsers talk directly, and the signaling server drops out.
The difference is what flows through the pipe. A video call streams camera frames. A file transfer streams the file. And streaming a multi-gigabyte file through a data channel turns out to involve two problems that video does not have: how to pace the bytes, and where to put them as they arrive.
How it works, part two: chunks and backpressure
You cannot simply hand a 4 GB file to the data channel and say "send this." A few things would break at once: the browser would try to read the entire file into memory, the send buffer would balloon, and the connection would choke.
So the file is broken into chunks, small pieces of a few kilobytes each, and sent one after another. This is the easy half. The hard half is pace.
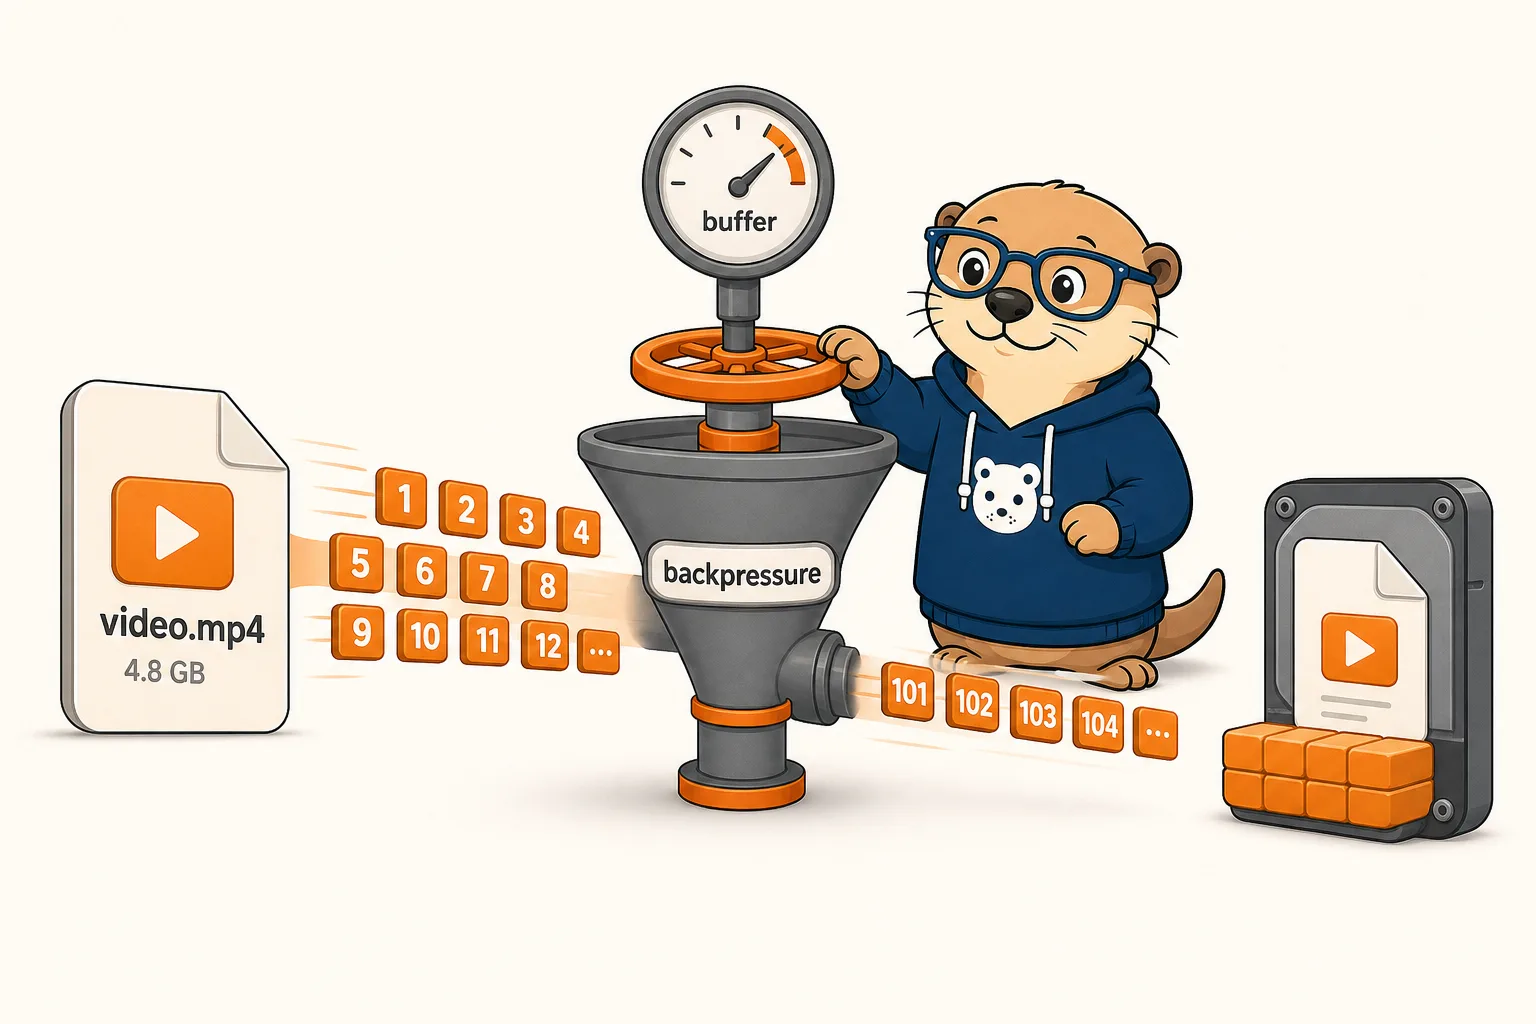
Imagine pouring water into a funnel faster than it can drain. It overflows. The same thing happens if the sender pushes chunks into the data channel faster than the network can carry them away: the browser's internal send buffer fills up without bound, memory balloons, and eventually the page crashes. The sender is fast (reading from a local disk); the network is slow by comparison. Something has to throttle the fast side to match the slow side.
That something is backpressure, and the data channel exposes exactly the gauge you need: a property called bufferedAmount, the number of bytes currently waiting in the send buffer, not yet handed to the network. The sending logic watches this gauge. When it climbs above a high-water mark, the sender pauses, stops reading new chunks from the file, and waits. When the buffer drains below a low-water mark (signaled by a bufferedamountlow event), it resumes. The result is a self-regulating flow: the sender automatically runs exactly as fast as the network can drain, and never an ounce faster.
This is the same idea as TCP flow control, one of the foundational concepts in networking, surfacing in a browser API. Get it wrong and large transfers crash; get it right and a 10 GB file streams through a few kilobytes of buffer at a time, using almost no memory. Pacing, not raw speed, is what makes big transfers possible.
How it works, part three: writing to disk, not to memory
The second problem is the receiving side. The chunks are arriving, where do they go?
The naive answer, "collect them all in memory and save at the end," fails for exactly the reason you would expect: you cannot hold a 10 GB file in a browser tab's memory. The tab would run out of RAM long before the transfer finished. For years this was the hard ceiling on browser file transfers, you could only receive a file small enough to fit in memory.
The fix is a newer browser capability called the File System Access API. With the user's permission (a single "where should I save this?" prompt), the receiving browser opens a writable stream straight to a real file on disk and writes each chunk to it as it arrives, then immediately forgets that chunk. At no point does the whole file exist in memory. The browser becomes a thin pipe between the network and the disk: bytes come in, bytes go to the file, nothing accumulates. This is what lifts the size limit. A file larger than your RAM, larger than the browser could ever hold, streams through cleanly because it is never held at all, only passed through.
(On browsers that do not yet support direct disk streaming, a transfer falls back to a more limited in-memory or chunked approach, which is why a tool may behave differently across browsers for very large files.)
How it works, part four: surviving an interruption (resumable transfers)
A 10 GB transfer takes a while, and in that window the Wi-Fi can drop, a laptop can sleep, a browser can be closed by accident. If the whole transfer had to restart from zero every time, large files would be hopeless. So a well-built tool makes transfers resumable.
The mechanism is elegantly simple. Because the receiver is writing chunks to a real file in order, it always knows exactly how many bytes it has durably written, call that the offset. If the connection breaks and is re-established, the receiver tells the sender "I already have the first N bytes, start again from offset N." The sender skips ahead and continues. The bytes already on disk are kept; only the missing tail is sent. A transfer manifest (the file's name, size, and identity) lets both sides confirm they are talking about the same file before resuming, and any stale bytes past the agreed offset are truncated so the file is never corrupted by a half-written chunk.
This capability is negotiated when the two browsers first connect (each advertises whether it supports resuming), so resume only kicks in when both sides can honor it. The payoff is real: a dropped connection becomes a pause, not a catastrophe.
Is it private? The encryption and the missing server
As with a video call, WebRTC data channels are encrypted by mandate, using DTLS, with keys negotiated directly between the two browsers. Combined with the fact that the file travels directly, peer to peer, and is never uploaded to or stored on any server, this gives a strong privacy property: the file exists only on the sender's device and the receiver's device, and the bytes in between are encrypted end to end.
Contrast this with the cloud-drive route, where your file is uploaded to a vendor's servers, stored there as a copy (sometimes long after you think you deleted it), and governed by that vendor's retention and scanning policies. We traced that lifecycle in detail in what actually happens when you upload a file online, and the short version is: an uploaded file is a file you no longer fully control. A direct transfer never creates that copy in the first place. The most private file is the one that was never uploaded, the same principle behind why your files should never leave your browser.
Why there is no size limit (and what the real limits are)
People are sometimes surprised that a browser tool has no file-size cap, when every cloud service does. The reason is structural. Cloud services cap size because they have to store your file, and storage costs money, so they meter it. A direct transfer stores nothing, so there is nothing to meter. The file streams from one disk to another and is gone from the wire the moment it arrives.
The real limits are physical, not policy:
- Your upload speed. A direct transfer can only go as fast as the sender's connection can push bytes out. This is the usual bottleneck.
- Both devices staying awake. Because there is no server holding the file, both browsers must be open and connected for the duration (or resume the transfer later). You cannot "upload now, let them grab it next week", that is the one genuine convenience a cloud copy buys.
- Browser support for disk streaming, for the very largest files, as noted above.
For sending a large file to someone who is ready to receive it, none of these are a problem. For "drop a file somewhere and forget about it," a stored cloud copy is still the right tool. Pick the model that matches the job.
Frequently asked questions
Do I need an account or an app? No. It runs in your browser, with no sign-up. You share a code or link, the other person opens it, and the transfer begins.
Is there a maximum file size? No fixed limit. Because nothing is stored on a server, there is no storage quota. Practical limits are your connection speed and, for the largest files, your browser's support for streaming directly to disk.
Is my file encrypted? Yes. WebRTC data channels are always encrypted, with keys negotiated directly between the two browsers, and the file never passes through a server, so the transfer is end-to-end encrypted.
What happens if my connection drops mid-transfer? If both browsers support resumable transfers, the receiver keeps the bytes already written to disk and the sender resumes from where it left off, rather than restarting. A drop becomes a pause.
Can the recipient download the file later, when I am offline? Generally no, and this is the key tradeoff. Because there is no server holding a copy, both people need to be connected at the same time (or resume later). For "leave it for them to grab whenever," a stored cloud link is the better fit.
Does the file get held in my browser's memory? On browsers that support streaming to disk, no, each chunk is written straight to the file and discarded, so even files larger than your RAM transfer cleanly. Older browsers may fall back to a more memory-bound approach.
The bigger picture
A direct file transfer looks mundane, you drop a file, someone else gets it, but it quietly solves a stack of real problems. It removes the upload wait by sending and receiving at once. It removes the size cap by storing nothing. It removes the server-side copy, and with it the privacy and retention worries that come from handing your file to a third party. And it does all this with browser technology that is already installed on the device in your hand: a peer connection, an encrypted data channel paced by backpressure, and a stream that writes straight to disk.
The thread running through it is the same one that runs through every privacy-first web app: take the middleman out. Your file goes from your device to theirs, encrypted, and then it is gone from everywhere in between. That is the whole idea, explored more broadly in the rise of privacy-first web apps.
If you have a file to send, drop it and share the link. The same direct, encrypted, browser-to-browser approach powers video calls and real-time whiteboards. Different surface each time, same principle: straight from your device to theirs, with no one in the middle.