 TabTasker
AI in your browser? Yes, really.
Imagine opening a website, clicking a button, and watching artificial intelligence transcribe an hour of audio, blur every face in a family photo, or summarise a 40 page PDF, all without your file ever leaving your laptop. No upload bar, no "we value your privacy" pop-up, no cloud account. Just your browser, your device, and a model doing the work right there in the tab.
That, in plain English, is client-side AI. It is sometimes called in-browser AI, on-device AI, local AI, or edge AI. The names differ, the idea is the same: the model that does the thinking lives on your computer, not on someone else's server.
For most of the last decade, AI on the web meant the opposite. You opened a tool, it asked you to upload a file, the file flew across the internet to a data centre, a huge model crunched it, and a response flew back. It worked, but it came with three quiet costs. Your data left your device. You needed a stable internet connection. And somebody, somewhere, was paying for every request, usually by passing the cost on to you, by selling ads, or by training on what you sent.
Client-side AI removes all three of those costs in one move. The model runs where you are. Nothing leaves. Nothing is logged. Nothing is metered.
Cloud AI vs client-side AI, at a glance
| Dimension | Cloud AI | Client-side AI |
|---|---|---|
| Where your data lives | Vendor server | Your device |
| Network required | Every request | Once, to download the model |
| Per-request cost | Metered, scales linearly | Zero after first load |
| Rate limits and quotas | Yes, tier-dependent | None beyond your own hardware |
| Logging and retention | Governed by vendor policy | Not possible, nothing leaves |
| Offline use | Impossible | Full capability |
| Cold start | Instant | Slow first time, instant after |
| Frontier capability | Highest | Catching up fast, very close on common tasks |
The everyday version: what does this actually feel like?
Picture three small moments.
A parent wants to post a photo from the school play without showing other children's faces. On a typical cloud tool, that photo gets uploaded to a stranger's server. With client-side face blurring, the detector runs in the browser, finds every face, and blurs it before the image ever moves. The "save" button writes the result back to the same folder it came from. Nothing ever travelled.
A freelance journalist records a two hour interview and needs a transcript before deadline. Cloud transcription services often charge by the minute and store the audio for "quality" reasons. A client-side Whisper model runs the same transcription in the browser, on the laptop, on the train, with no signal. The audio file never leaves the device, and the only cost is the few seconds the GPU spends working.
A small business owner needs to redact bank details from a PDF before sharing it with an accountant. Online redaction tools quietly keep a copy of every page. A client-side tool opens the PDF in the browser, lets the user black out the sensitive bits, and saves a clean copy back to the desktop. The original document never crossed the public internet.
These are not science-fiction examples. They are tools that already exist today on TabTasker and other privacy-first web apps. The technology underneath them is what the rest of this article is about.
How is this possible at all?
A reasonable question. A browser is, historically, a document viewer. How did it become a place where multi-hundred-megabyte neural networks run at near-native speed? The short answer is that three previously separate technologies grew up and started cooperating.
WebAssembly, the universal runtime
WebAssembly, almost always shortened to Wasm, is a low-level instruction format that browsers can execute at speeds close to native machine code. It is not a language. It is a compilation target. Code written in C, C++, Rust, or Go can be compiled to Wasm and run inside any modern browser without a plug-in.
For AI, this matters because the mature inference engines, the libraries that actually multiply matrices and apply activation functions, were already written in C++ and Rust. ONNX Runtime, llama.cpp, GGML, and the kernels that power Hugging Face's Transformers.js were not written from scratch for the web. They were ported. Wasm gave them a door into the browser without forcing a rewrite, and that single fact compressed years of porting work into months.
WebGPU, the parallel maths engine
CPUs are general-purpose. They are extraordinarily good at branching logic, but they handle one or two streams of arithmetic at a time. Neural networks need the opposite: millions of small multiplications, all independent, all happening at once. That is exactly what graphics processing units were built for.
WebGPU is a new browser API, the successor to WebGL, that gives JavaScript and Wasm direct, structured access to the GPU. Before WebGPU, browser-based AI was bottlenecked on the CPU. With WebGPU, the same models run between ten and one hundred times faster, depending on the workload. A Whisper transcription that takes sixty seconds on CPU often takes five seconds on WebGPU. That is the difference between "interesting demo" and "tool I will actually use".
Chrome and Edge have shipped WebGPU. Safari has it behind a flag and is moving toward default. Firefox is finishing its implementation. Within a year, WebGPU will be a near-universal browser feature.
Model optimisation, the great shrinking
The third leg of the stool is the work researchers have done to make models smaller without making them noticeably worse. Three techniques carry most of the weight.
Quantisation reduces the precision of model weights. A typical large model is trained in 32 bit or 16 bit floating point. Quantised versions store the same weights in 8 bit, 4 bit, or even 2 bit integers. Done well, the quality drop is tiny and the size drop is dramatic. A 7 billion parameter model that needs 28 GB at full precision can fit in roughly 4 GB at 4 bit, which puts it inside the memory budget of an ordinary laptop.
Pruning removes weights that contribute little to the final output. Many neurons in a trained network are nearly zero, and removing them changes almost nothing. Sparsity-aware inference engines can then skip the multiplications entirely.
Distillation trains a smaller "student" model to mimic a larger "teacher". DistilBERT, DistilBART, and TinyLlama are all products of this approach. They are typically a third to a half the size of their teachers and lose only a few percentage points on benchmarks.
Together, these techniques are why a model that would have demanded a data centre in 2020 now fits on a phone in 2026.
What quantisation does to a 7 billion parameter model
| Precision | Bits per weight | On-disk size | Typical quality drop vs FP16 |
|---|---|---|---|
| FP32 | 32 | ~28 GB | Reference, training precision |
| FP16 | 16 | ~14 GB | Baseline for comparison |
| INT8 | 8 | ~7 GB | Under 0.5% on most benchmarks |
| INT4 (GPTQ, AWQ) | 4 | ~3.8 GB | 1 to 2%, often imperceptible in chat |
| INT3 | 3 | ~2.9 GB | 3 to 5%, task-dependent |
| INT2 | 2 | ~1.9 GB | 5 to 10%, useful only for some workloads |
The INT4 row is the one that matters in practice. It is the precision at which a capable model fits in the memory budget of an ordinary laptop while still feeling sharp in conversation.
What can client-side AI actually do today?
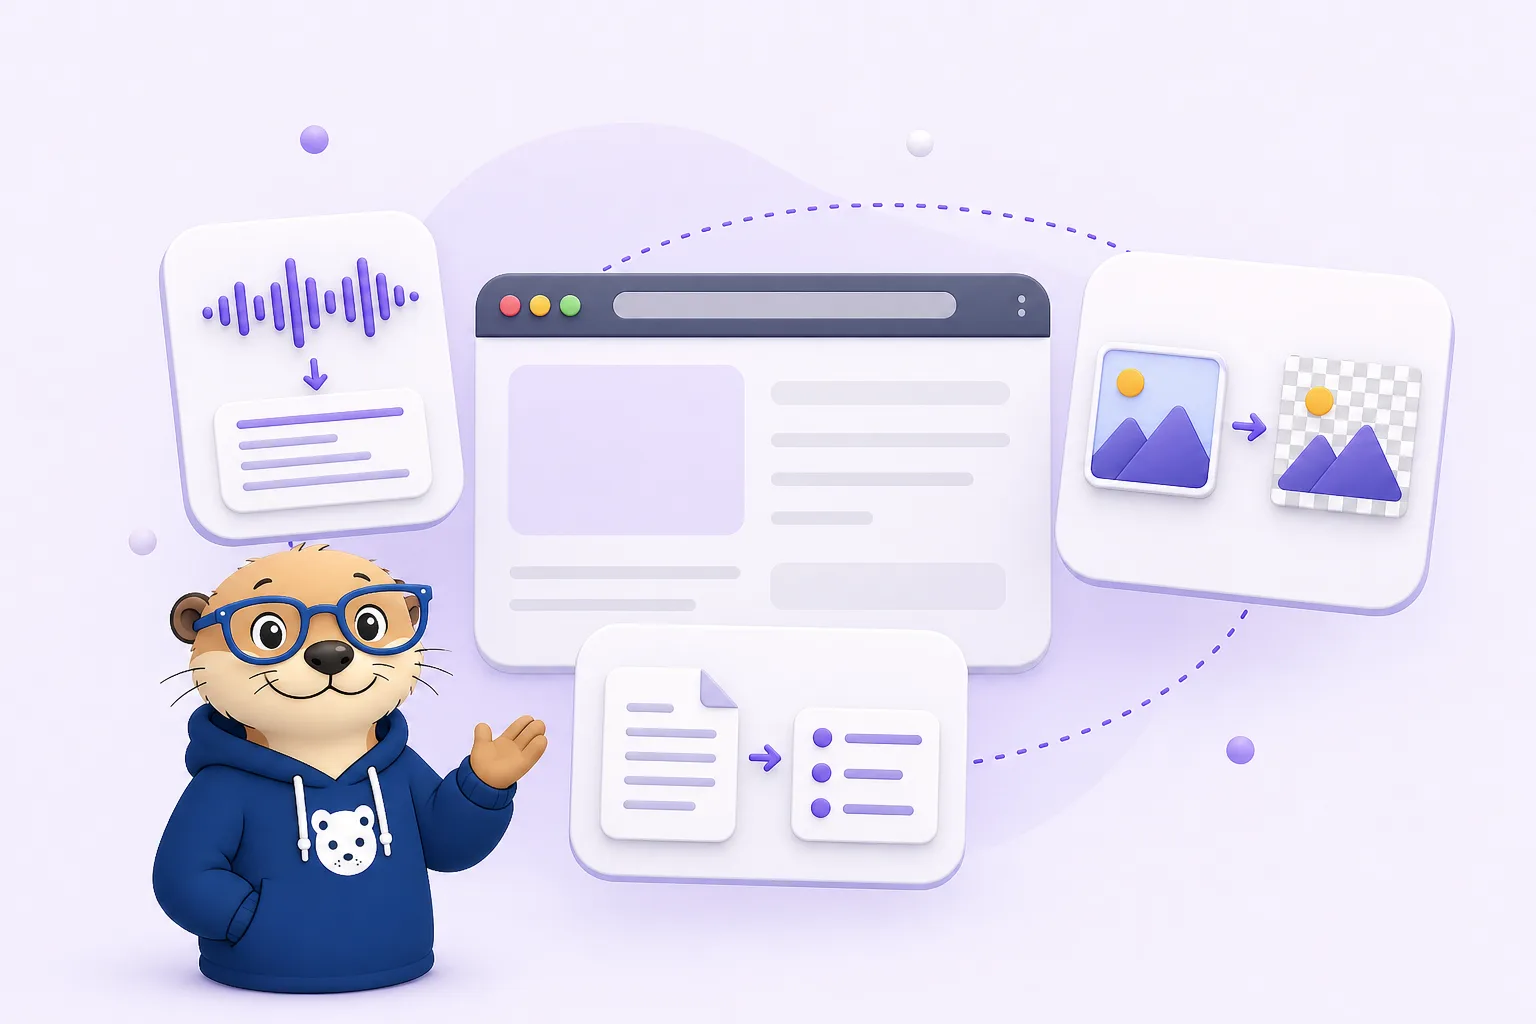
Here is the working list of capabilities that already run, in production, in a browser tab:
- Speech-to-text transcription with Whisper, including multilingual audio
- Background removal from images using segmentation networks
- Face detection and blurring for privacy-safe photo sharing
- Text summarisation with DistilBART and similar encoder-decoder models
- Sentiment analysis with DistilBERT
- Text-to-speech with SpeechT5 and other neural vocoders
- Image OCR with Tesseract and modern transformer-based recognisers
- Local LLM chat with small language models such as Phi, Gemma, and Llama variants
- Image upscaling with super-resolution networks
All of these are available, today, at TabTasker, running entirely in the browser.
Why client-side AI matters
Privacy, in the strong sense
The word "privacy" gets used loosely. Cloud services often mean "we encrypted it in transit" or "we deleted it after thirty days". Client-side AI means something much stronger: the data does not travel at all. There is no server to log it, no engineer who can access it, no breach to leak it, and no policy that can be quietly changed later. For regulated work in healthcare, law, finance, and journalism, that is not a marketing point. It is a compliance requirement.
Genuine offline capability
After the model is downloaded once, most client-side AI tools work without an internet connection. A journalist in a basement, a clinician in a rural clinic, a researcher on a flight, all of them can use tools that, on a cloud model, would simply refuse to load.
A cost curve that bends the right way
API pricing scales linearly with usage. Run a transcription a thousand times and you pay a thousand times. Client-side inference inverts the curve: a one-time download, then unlimited use. For high-volume workflows, the second model is dramatically cheaper, and the marginal cost of each additional request rounds to zero.
No rate limits, no quotas
Hosted APIs throttle. They have to, because their infrastructure has a ceiling. Your laptop has a ceiling too, but only you are using it, so the practical throughput for a single user is often higher than what a paid API tier will allow.
The trade-offs, honestly
Client-side AI is not a free lunch. Three real costs come with it.
- The initial download. Models range from around 50 MB for small classifiers to several gigabytes for capable language models. The first use is slow. Subsequent uses are not, because the model is cached.
- Hardware sensitivity. Bigger models want a recent CPU and, ideally, a WebGPU-capable GPU. On a five year old laptop, the experience is real but slower. On a current MacBook or a gaming PC, it is often faster than a cloud round-trip.
- A ceiling on capability. The very largest frontier models, the ones that handle long-context reasoning across thousands of pages, still live in data centres. Client-side models are catching up quickly, but for the highest-end research tasks, the cloud still wins.
Model caching, the quiet hero of the user experience
A 300 MB download sounds like a deal-breaker. It is not, because it happens exactly once.
Modern browsers expose a storage layer called IndexedDB that, alongside the newer File System Access API and the Cache Storage API used by service workers, lets a web app store hundreds of megabytes of binary data persistently and retrieve it in seconds. Inference libraries such as Transformers.js and ONNX Runtime Web write model weights into that storage on first load and read them back on every subsequent visit. The download bar appears once. After that, the model "boots" in a second or two, every time.
This is structurally different from a cloud API. Every cloud request pays the network and queue cost in full. Every client-side request after the first one is local, instant, and free.
WebGPU, in more detail: why it changes the shape of what is possible
CPU inference was the original bottleneck. A typical multi-head attention layer over a long sequence does billions of multiply-accumulate operations. A modern CPU can do this, but in serial chunks. A GPU does the same work in parallel waves, scheduling thousands of threads at once across hundreds of execution units.
WebGPU exposes that hardware through a clean, modern API. It supports compute shaders written in WGSL, structured binding of buffers, and explicit control over memory layout. For an inference library, this means the same kernel that runs on a desktop Vulkan, Metal, or D3D12 backend can be lowered to WGSL and run in the browser with very little quality loss.
The practical result, in numbers: speech recognition that was minutes becomes seconds, image generation that was infeasible becomes interactive, and small language models that were toy demos become drafting assistants you can chat with in a browser tab. WebGPU is the single technology that moved client-side AI from "interesting" to "usable for real work".
If your browser supports it, the AI tools on TabTasker automatically offer GPU acceleration, and the performance difference is dramatic.
Measured speedups, CPU versus WebGPU
| Workload | CPU only | WebGPU | Speedup |
|---|---|---|---|
| Whisper transcription, 60 min audio | ~58 s | ~6 s | ~9.7x |
| DistilBART summary, 4,000 token article | ~12 s | ~1.4 s | ~8.6x |
| Phi-3 mini chat reply, 256 tokens | ~22 s | ~2.1 s | ~10.5x |
| Background removal, 4K photo | ~9 s | ~0.8 s | ~11.3x |
| OCR pass, 20 page PDF | ~31 s | ~3.5 s | ~8.9x |
Numbers above are typical on a mid-range 2024 laptop, M-series Mac or RTX-class Windows machine. The exact figures vary by hardware, but the order of magnitude is consistent: WebGPU turns "wait and watch the spinner" into "tap and it is done".
A more academic framing: what is really happening here
For readers who want the deeper picture, a more formal framing helps.
Inference as a deployment topology problem
Machine learning systems are usually described by the model. They are better described by the deployment topology, the question of where each tensor lives at the moment of inference. Cloud inference colocates weights, activations, and input data in a single remote process. Client-side inference moves the weights to the user's device while keeping the input data local. The activations, the intermediate tensors produced during a forward pass, are produced and destroyed on the device. The privacy properties fall directly out of this topology. The input never traverses an untrusted network, so the threat model collapses from "the entire path between user and provider" to "the user's own device".
Why model size is no longer the binding constraint
For most of the deep learning era, model capability scaled smoothly with parameter count. That relationship has weakened. Modern small models, in the 1 to 8 billion parameter range, benefit from three independent improvements: better data curation, longer training schedules, and architectural refinements such as grouped-query attention, mixture-of-experts routing, and state space modules like Mamba. The net effect is that capability per parameter has been rising sharply. A 4 billion parameter model in 2026 routinely outperforms a 70 billion parameter model from 2023 on practical benchmarks. This is the underlying reason that client-side AI is suddenly viable. The capability frontier has moved closer to the device.
The shift is clearest when capability is plotted against parameter count over time. Smaller, newer models are catching, and in many cases passing, much larger predecessors.
| Model | Year | Parameters | MMLU-style score | Capability |
|---|---|---|---|---|
| GPT-3 davinci | 2020 | 175B | ~43 | ████████░░░░░░░ |
| LLaMA 1 7B | 2023 | 7B | ~35 | ██████░░░░░░░░░ |
| LLaMA 1 70B | 2023 | 70B | ~63 | ████████████░░░ |
| Mistral 7B | 2023 | 7B | ~60 | ███████████░░░░ |
| Llama 3.2 3B | 2024 | 3B | ~63 | ████████████░░░ |
| Phi-3 mini | 2024 | 3.8B | ~69 | █████████████░░ |
| Phi-4 mini | 2025 | 4B | ~74 | ██████████████░ |
| Gemma 3 4B | 2025 | 4B | ~72 | ██████████████░ |
The pattern is clear. The 4 billion parameter row at the bottom of the table is the size that downloads in a minute or two, runs comfortably on a laptop, and scores higher than the 175 billion parameter cloud model that launched the modern AI era six years earlier.
Quantisation as a first-class research field
Quantisation began as a deployment trick. It has matured into a research discipline. Techniques such as GPTQ, AWQ, and SmoothQuant carefully redistribute quantisation error across layers to preserve accuracy. Mixed-precision schemes keep the most sensitive layers in higher precision while pushing the rest down to 4 or 2 bits. Calibration datasets are now curated with as much care as training datasets. The result is that a well-quantised 4 bit model loses, in many cases, less than one percent on standard benchmarks compared to its full-precision equivalent, while occupying roughly an eighth of the memory.
The role of WebGPU compute in the broader stack
WebGPU is sometimes treated as a graphics API. It is more usefully understood as the browser's first true general-purpose GPU compute interface. It exposes work groups, shared memory, atomics, and structured storage buffers in a way that maps cleanly onto the abstractions used by CUDA, Metal, and Vulkan compute. Inference libraries can therefore share a single kernel design across native and web targets, which has accelerated the porting work considerably. The browser is no longer a special case, it is one backend among several.
A realistic two year forecast
Extrapolating current trends, three things are likely within roughly two years.
First, frontier-quality capability on common tasks, summarisation, translation, transcription, code completion, structured extraction, will run locally on average consumer hardware. The frontier itself will still live in data centres, but the gap between frontier and local will shrink to the point where most users no longer perceive it.
Second, WebGPU will be a near-universal browser feature, and a follow-on standard, sometimes referred to in working groups as WebNN, will offer a higher-level neural network primitive layer that further closes the gap with native inference.
Third, the privacy argument will move from being a developer preference to being a procurement requirement. Regulated industries are already asking vendors whether their AI features run on-device. Within two years, the answer will routinely be yes.
The bottom line
Client-side AI is not a niche. It is a structural shift in how machine learning is delivered to people. The same model that, in 2022, required a paid API key and a network round-trip can, in 2026, run silently inside a browser tab. The data stays where it started. The cost stops at the download. The capability is good enough for the overwhelming majority of real work, and improving every month.
The cloud AI model is not going away. For the very largest, very newest capabilities it will remain dominant. But for everyday tasks, transcribing, summarising, redacting, extracting, generating, editing, the centre of gravity has already moved to the device. Privacy-first web apps such as TabTasker are not waiting for that shift. They are it.
And when AI runs on your device, you control your data. Always.