 TabTasker
The same five clicks, every single week
Every Monday you do the same thing. Take last week's report PDFs, compress each one, stamp a watermark on every page, merge them into a single file, and rename the result. It is not hard. It is just ten minutes of clicking the same buttons in the same order, forever. The work is mindless, which is exactly why it is so easy to get wrong: skip a step, compress the wrong file, forget the watermark on page three.
Computers are supposed to be good at exactly this kind of repetitive, ordered work. The trouble is that automating it usually means either writing a script (which most people cannot) or wiring up a cloud automation service that wants your files uploaded to its servers and a monthly subscription for the privilege.
There is a third option: a workflow you build once, visually, in your browser, by connecting tools together like train cars, and then run with a single click, forever, with your files never leaving your device. Drop the PDFs in, and compress, watermark, merge, and rename all happen in order, automatically, locally.
This guide is about that idea. It starts with the everyday "do this for me" and works down to the computer-science underneath: dataflow programming, directed acyclic graphs, and topological ordering, the same concepts that power industrial data pipelines, running quietly inside a browser tab. Read as far as you find useful.
If you want to try it, TabTasker's workflows let you chain tools into a one-click pipeline that runs entirely in your browser. The rest of this article explains what is really happening when you press run.
The everyday version: what is a workflow?
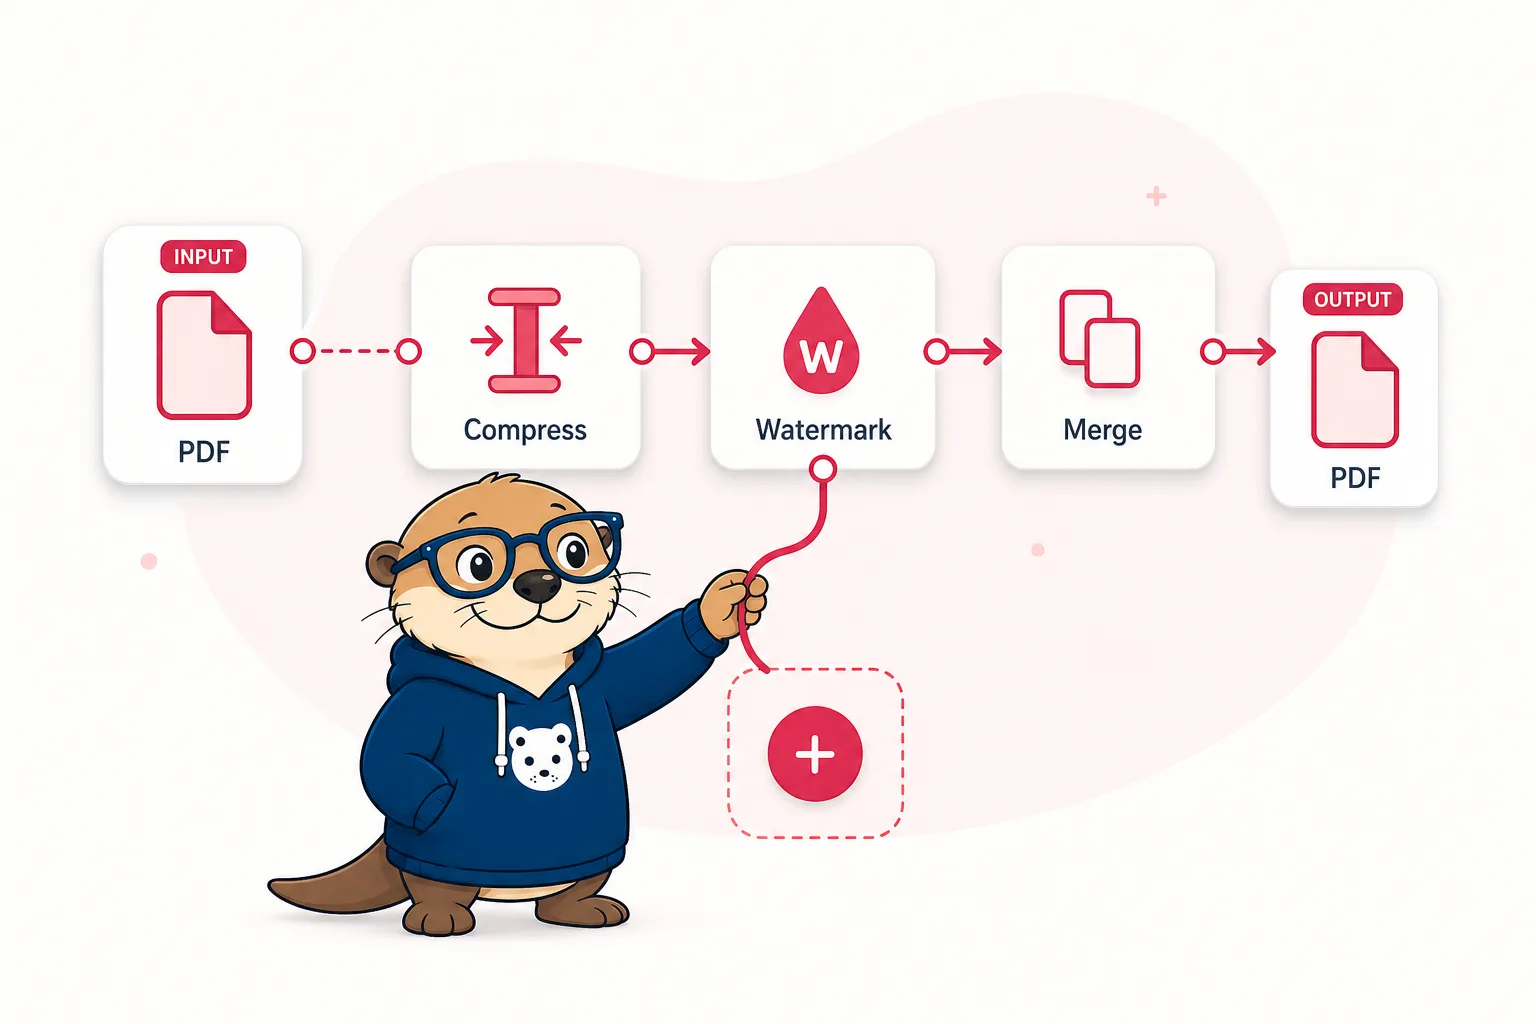
A workflow is a recipe made of tools. Instead of doing five steps by hand, you arrange those five steps once, draw arrows showing what feeds into what, and save it. After that, the whole sequence is a single button.
Three plain promises make it useful.
First, it chains tools together. Each step is a small tool you already understand, compress, watermark, merge, convert, resize, transcribe, and the workflow is just those tools connected in order, with the output of one becoming the input of the next.
Second, it runs in one click. Once the recipe is built, you drop your files in and every step fires automatically, in the right order, without you babysitting it. The ten-minute Monday chore becomes a two-second action.
Third, it is reusable and shareable. A workflow is a thing you save. You can run it again next week, export it as a file, or send it as a link so a colleague can run the exact same pipeline on their own files, on their own device.
Here is how that compares to the other ways people handle repetitive tasks.
| Approach | Who can do it | Where your files go | Reusable | Setup cost |
|---|---|---|---|---|
| Doing it by hand | Anyone | Stay local | No, repeat every time | None, but endless |
| Writing a script | Programmers only | Stay local | Yes | High, needs coding |
| Cloud automation (Zapier, Make) | Most people | Uploaded to the service | Yes | Medium, plus subscription |
| Browser workflow | Anyone | Stay in your browser | Yes | Low, visual building |
The sweet spot is the bottom row: the reusability of a script and the privacy of doing it by hand, with the ease of dragging boxes and drawing arrows. No code, no upload, no subscription.
Who uses this, and for what
An office manager turns the weekly report ritual, compress, watermark, merge, into one button and never misses a step again.
A content creator builds a pipeline that takes a raw recording, trims silence, normalizes the audio, and exports it ready to publish, then reuses it for every episode.
A small business standardizes how invoices are processed, the same conversion and stamping applied identically to every document, so the output is consistent no matter who runs it.
A team shares a single workflow file so everyone processes files the same way, turning a tribal "here is how we do it" into an executable recipe anyone can run.
The common thread is repetition with structure: a task you do more than once, the same way each time. That is precisely what a workflow captures.
How it works, part one: nodes and wires are a graph
When you build a workflow, you are doing something more formal than it looks. Each tool is a node, a box that takes some input and produces some output. Each arrow you draw is a wire (an edge) that carries the output of one node into the input of the next. What you are drawing, in the language of mathematics, is a graph: a set of nodes connected by directed edges.
This is the same structure as a whiteboard architecture diagram, but with a crucial difference: these boxes do something. The diagram is not a picture of a process; it is the process. This style of programming, where you describe a computation as data flowing through a network of operations, has a name: dataflow programming. It is how visual tools from audio synthesizers to machine-learning pipelines to industrial ETL systems are built, and it is powerful for one big reason: humans are far better at understanding "this feeds into that feeds into that" as a picture than as a page of nested code.
The direction of the wires matters enormously. A wire from Compress to Watermark means "compress first, then watermark." Reverse it and you watermark first, then compress, which might blur your watermark. The arrows encode not just connection but order and dependency.
How it works, part two: the DAG and the order of operations
There is one rule a workflow must obey, and it is worth understanding because it explains both what workflows can do and what they cannot.
The graph must be a DAG: a Directed Acyclic Graph. "Directed" means the wires have arrows (data flows one way). "Acyclic" means there are no loops, you cannot have A feed into B feed into C feed back into A. The reason is simple if you think about it: if A needs B's output, and B needs A's output, neither can ever start. It is a chicken-and-egg deadlock. Forbidding cycles is what guarantees the workflow can actually run to completion.
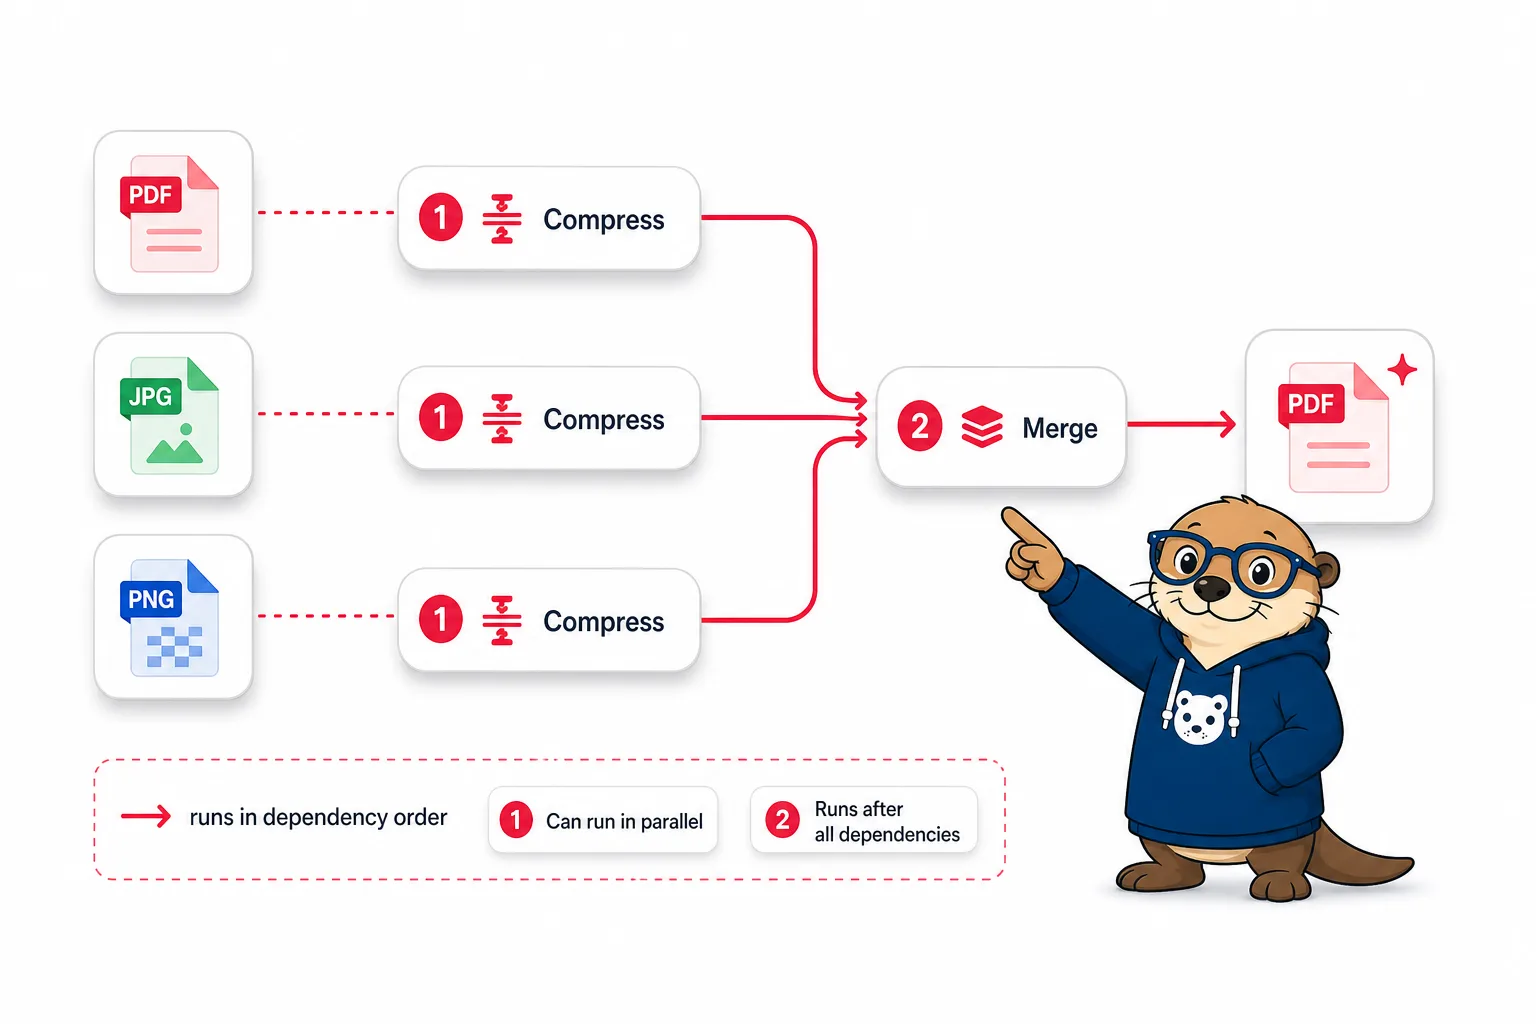
Given a valid DAG, how does the system know what order to run the steps in? It uses an algorithm called a topological sort. The idea is intuitive: a step can only run once all the steps feeding into it have finished. The compress step can run immediately because it only needs your input file. The merge step must wait until every file it combines has been produced. A topological sort is just a formal way of finding an order that respects every one of these dependencies.
This unlocks something nice: steps that do not depend on each other can run in parallel. If your workflow compresses three separate files and then merges them, all three compressions can happen at once, and only the merge has to wait. The DAG structure makes this parallelism automatic, the system can see, just from the shape of the graph, which work is independent. The same structure that organizes a giant data center's processing jobs organizes your Monday PDF chore.
How it works, part three: why running it locally changes everything
Here is where a browser workflow diverges sharply from a cloud automation service like Zapier or Make, and the difference is not a minor feature, it is the whole philosophy.
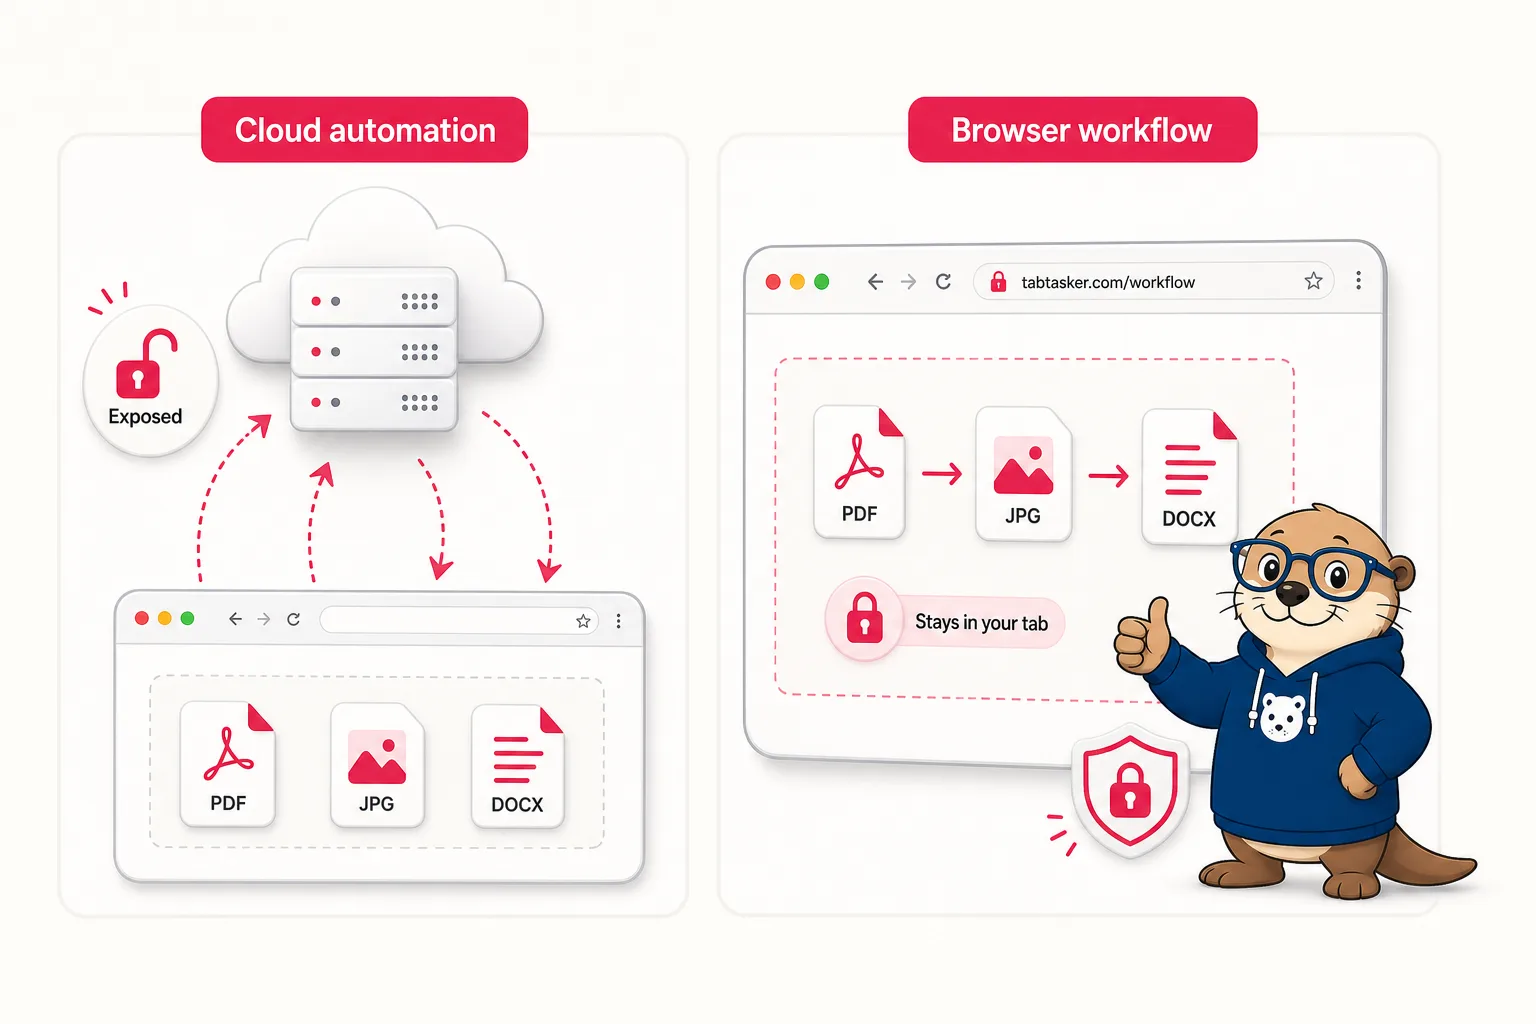
A cloud automation service runs on someone else's servers. For it to compress your PDF, your PDF has to travel to its data center, get processed there, and travel back. Every file in every run passes through, and is at least momentarily stored on, infrastructure you do not control. For automating public data, fine. For automating your invoices, contracts, medical records, or unreleased work, you have just handed all of it to a third party, on a schedule, automatically. We traced exactly what that costs in what actually happens when you upload a file online.
A browser workflow runs on your machine. Every node, the compressor, the watermarker, the merger, is code executing inside your own browser tab, working on files that never leave your device. There is no upload step because there is no server to upload to. There are no quotas, because nobody is paying to store or process your data, you are. And there is no privacy policy to read, because nothing leaves to be governed by one. This is the same conviction behind every TabTasker tool, laid out in why your files should never leave your browser.
The tradeoff is honest and worth stating: a cloud service can run your automation while your computer is off, triggered by an incoming email or a calendar event on its servers. A browser workflow runs when you run it, because it lives where you are. For the enormous category of "I have these files, do the usual sequence to them," that is exactly the right model. For "watch my inbox forever and react at 3am," the cloud still wins. Match the tool to the job.
How it works, part four: every step is glass, not a black box
A subtle but important property of a well-built workflow is that it is inspectable. Because each node produces a real, concrete output, you can look at the result of every intermediate step, not just the final file. After a run, you can see what the compressor produced, then what the watermarker did to it, then what the merge combined.
This matters for trust. When a single button does five things, the natural worry is "what if step three went wrong and I do not notice until the end?" An inspectable workflow answers that by showing its work at each stage. If the watermark landed in the wrong place, you see it at the watermark step, not after you have already shipped the merged file. The pipeline is a series of glass boxes, not one opaque machine. This is the same value a scientist gets from showing intermediate calculations: a result you can audit is a result you can rely on.
Templates, reuse, and portability
The real payoff of workflows is not building one, it is never building it again. A workflow is saved state, and that opens three doors.
Templates give you a head start: common pipelines (a document-processing chain, an audio-cleanup chain) come pre-built, so you adapt rather than start from a blank canvas. The recurring shapes of real work, captured once, ready to reuse.
Reuse is the core loop: build the Monday pipeline once, run it every Monday with new files. The setup cost is paid a single time and amortized across every future run.
Portability makes it social: because a workflow is just data describing nodes and wires, it can be exported as a file or shared as a link. A colleague opens it and runs the identical pipeline on their own machine, their own files, no setup. A workflow becomes a way to share a process, not just a result, turning "let me explain how I do this" into "here, run this."
When a workflow is the right tool (and when it is not)
Reach for a workflow when the task is repetitive, multi-step, and ordered: the same sequence of tools applied to new files on a recurring basis. That is its home turf, and it shines there.
Be realistic about its edges. A browser workflow is not the right tool for event-driven automation that must run while you are away (an incoming-email trigger at midnight), for tasks that need a live external service mid-pipeline, or for genuinely branching logic far beyond a fixed sequence. Those are jobs for server-side automation, with the privacy tradeoff that implies. The browser workflow's promise is narrower and, for most everyday file work, more valuable: take the manual ritual you already do, and make it one private, repeatable click.
Frequently asked questions
Do I need to know how to code? No. You build a workflow visually, by adding tool nodes and drawing wires between them. There is no programming involved.
Do my files get uploaded anywhere? No. Every step runs inside your browser on your device. Files never leave your tab, there are no uploads, no accounts, and no quotas.
How is this different from Zapier or Make? Those are cloud services: your data flows through their servers, and they can trigger automations on a schedule even while your computer is off. A browser workflow runs locally, privately, and on demand, your files stay with you, but it runs when you run it, not on its own in the background.
Can I reuse a workflow, or share it? Yes. A workflow is saved and reusable, and you can export it as a file or share it as a link so someone else can run the identical pipeline on their own files.
Can I see what each step did? Yes. Each node produces a concrete output, so you can inspect every intermediate result, not just the final one, which makes it easy to catch a problem at the exact step where it happened.
What kinds of tools can I chain? Document, image, audio, and developer utilities, anything from compressing and watermarking a PDF to converting and cleaning up audio, composed into a single pipeline.
The bigger picture
A workflow looks like a row of connected boxes, but it is really a small, honest piece of computer science doing useful work. The boxes form a directed acyclic graph. A topological sort runs them in dependency order and parallelizes whatever is independent. Each node is a glass box you can inspect. And the whole thing executes on your own machine, so the convenience of automation does not cost you the privacy of your files.
The deeper idea is that automation should not require a choice between capable and private. The cloud taught us that to automate something, you must send it away. A browser workflow quietly rejects that premise: the same dataflow pipeline that organizes industrial computing can run in the tab in front of you, on files that never move. You get the leverage of a machine doing the boring parts, without handing your work to anyone.
If you have a task you do the same way every week, build it once and run it with a click. For a gentler, example-led introduction, see how TabTasker workflows work. And the same browser-only principle powers real-time whiteboards, video calls, and direct file sharing: your work, your device, no upload required.